Meta’s Muse Ember looks cheap on paper — but the release still leaves key economics unresolved
What Meta’s Muse Ember release actually proves about cost, context limits, and benchmark comparisons for agent workloads.
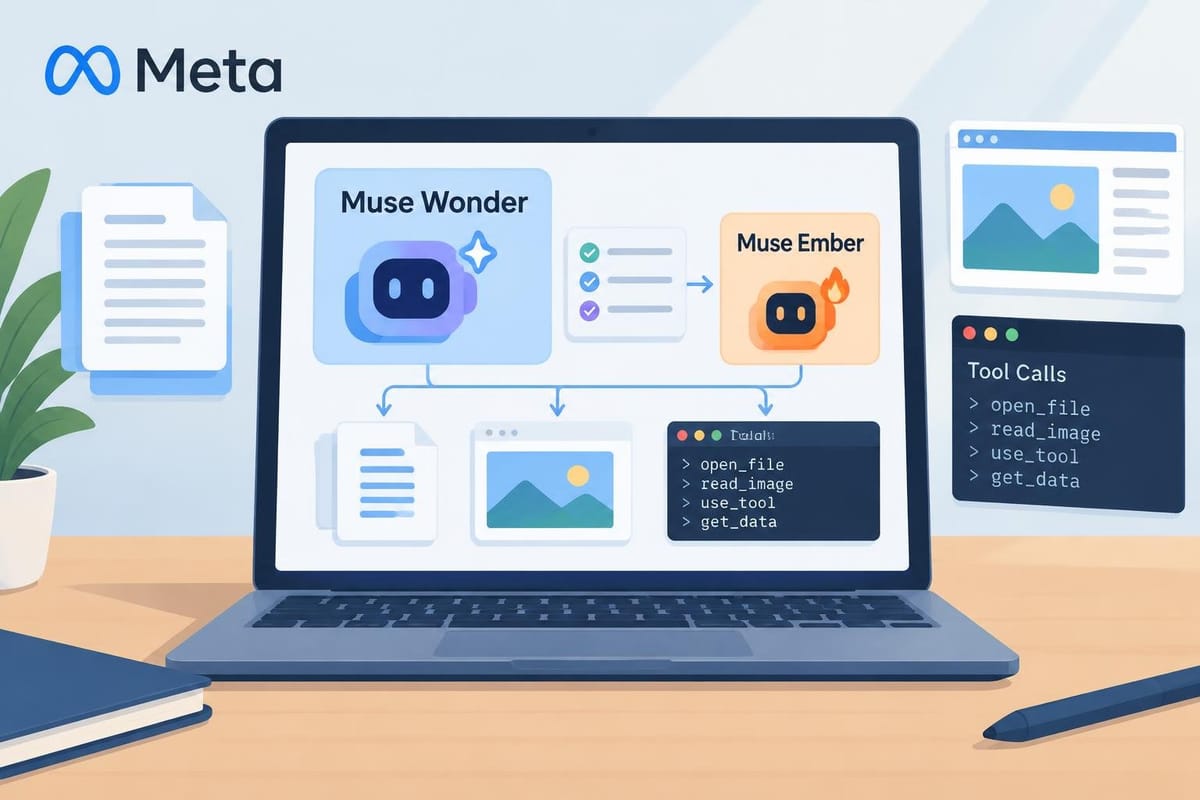
Meta’s new Muse Ember model is being sold as a bargain for agent workloads: the smallest model in the Muse line, priced at $0.10 per million input tokens, and pitched as the answer to repetitive jobs like tool calls, routing, extraction, and long-document parsing. But the release materials that are public today do not prove a broad “cheaper route to agent execution” claim. They show a narrower argument: Ember may be a lower-cost way to handle a specific slice of agent work, under Meta’s own benchmark and deployment assumptions, but the evidence is not enough to conclude it is a like-for-like replacement for larger models across real production systems.
Meta’s official launch post says Ember is “our smallest and most efficient model,” designed for “complex reasoning execution and the work agents repeat all day.” TechCrunch’s read of the announcement says Meta is emphasizing cost-per-task, not just raw capability, and that the company positions Ember at 10 cents per million input tokens as a cheaper alternative to Anthropic’s Haiku and OpenAI’s Luna, while also comparing it with open-source models such as DeepSeek V4.1 Flash and GLM 5.3 Flash. Meta announcement, TechCrunch
That pricing headline is real, but it is also incomplete. The public release materials surfaced in the reporting do not spell out the full pricing structure for all usage patterns, and the comparison breaks down once context length changes. A separate report notes a “200K catch,” indicating a step-up in cost past prompts up to 200,000 tokens. That matters because agent systems often become expensive not just because of output tokens, but because they accumulate long context, tool traces, retrieval results, and documents over many steps. Fello AI
That context matters more than Meta’s marketing suggests. If the model is cheap only within a shorter, cleaner prompt window, the economics can change quickly for the very workflows Meta says Ember is built for: document parsing, extraction, and repeated task execution. The release materials publicized in secondary coverage do not yet give a full accounting of latency assumptions, batching behavior, or how performance changes when the model is used in the kind of multi-step agent loop Meta is describing. Without that, “cheaper” is directionally true but operationally underspecified.
The benchmark framing has the same problem. TechCrunch says Meta used Artificial Analysis’s composite benchmark score to argue Ember is “cheaper and smarter” than rivals such as Anthropic’s Haiku and OpenAI’s Luna. But a composite index is not the same thing as a direct, task-by-task evaluation of an agent stack. It blends results across tests that may favor some model shapes over others, and it does not automatically tell you how a model behaves when it is embedded in a planner-executor system, handed long documents, or forced through repeated tool calls.
That distinction is important because Meta itself describes Ember as part of a two-model setup. In the company’s framing, a larger model such as Muse Wonder does the planning and decision-making while Ember handles volume: “Muse Wonder plans, Muse Ember handles the volume,” TechCrunch reports. That is a more modest claim than “Ember replaces larger models.” It suggests a narrow role for Ember inside a larger system, where the savings come from delegating routine execution to a smaller model after a bigger model has already done the hard thinking. TechCrunch
The deployment notes also hint at a broader but still bounded use case: Ember is said to handle text, images, and audio, including screenshots, charts, scanned documents, voice memos, and meeting recordings. That is useful for agents, but it still does not tell buyers what hardware is required, what throughput is realistic, or what latency budget Meta assumes when it says the model is efficient. The public materials quoted in coverage do not provide that operational detail.
For readers deciding whether this is a meaningful economics shift, the key takeaway is that Meta has publicized a compelling price point, but not yet a fully verified cost model for agent deployment. The company’s own framing appears to support a hybrid architecture: use a larger model to plan, then use Ember to carry out repetitive work at lower marginal cost. That is plausible and potentially useful. It is not the same as proving Ember is the cheapest or best option for all agent workloads.
The strongest evidence in the release is therefore narrower than the headline suggests. Ember looks designed for a specific job description: high-volume execution, not top-end reasoning. The public materials support that positioning. They do not yet prove a universal intelligence-per-dollar win against rival models across the messy, long-context, latency-sensitive reality of production agents.
What the release materials do support
- Ember is Meta’s smallest Muse model and is aimed at repetitive agent tasks. Meta, TechCrunch
- Meta says the model is priced at $0.10 per million input tokens. TechCrunch
- Meta’s own setup appears to pair Ember with a larger planner model, rather than replacing the planner outright. TechCrunch
- The public comparisons rely on benchmark composites, which are useful but not the same as end-to-end production agent tests. TechCrunch
- A separate report indicates pricing changes after 200,000 tokens, which weakens any simple cost-per-token pitch for long-context jobs. Fello AI
What remains unproven
- Full pricing for all context tiers and request patterns.
- Latency under real agent workloads.
- Hardware assumptions and deployment constraints.
- Whether the benchmark selection is truly like-for-like for planner-executor systems.
In other words, Meta has made a credible case that Ember can be cheaper for a class of routine agent tasks. It has not yet shown that the model’s economics hold up unchanged once workloads get longer, messier, and closer to production reality.
Comments ()