Cerebras Launches CS-4 as Rack-Scale Inference System, Promising Up to 30x Faster Performance Than GPUs
Cerebras has introduced CS-4 as a rack-scale inference system and says it can deliver up to 30x faster inference than GPUs. The launch materials leave benchmark and pricing details unresolved.
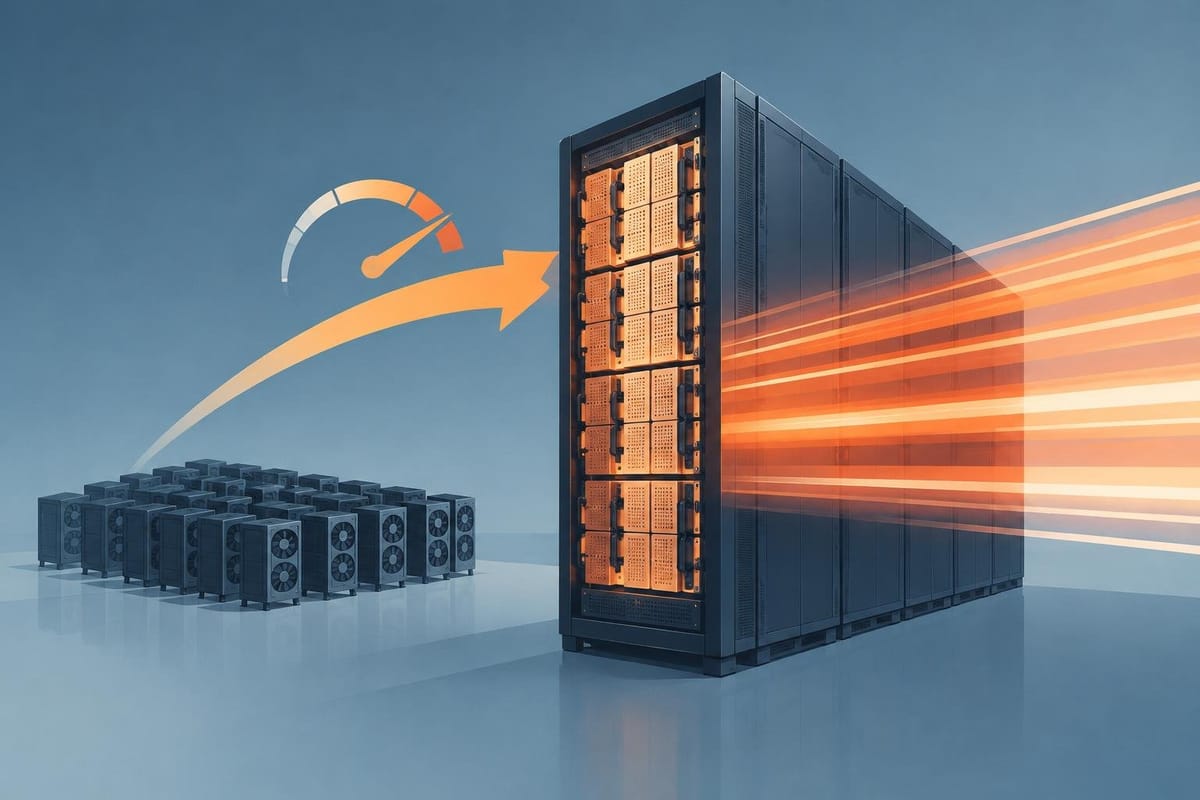
Cerebras is pitching CS-4 as a new rack-scale inference system, with the company’s homepage and inference page now centering the product around a claim of up to 30x faster inference than GPUs.
The launch materials say CS-4 is aimed at AI inference workloads and position it as part of Cerebras’ broader inference cloud and API offering. In search snippets captured from the company’s site, Cerebras says the system can “slash AI infrastructure costs compared to GPU clouds” while delivering “up to 30x faster inference,” and that users can “run leading models without waiting on slow GPU inference.” The homepage snippet also describes CS-4 as “a revolutionary rack-scale solution.”
What is clear from the public materials is the product framing. What is less clear is the exact basis for the 30x comparison. The materials we could verify do not spell out the benchmark setup, the specific GPU systems used for comparison, the model classes tested, or whether the claim refers to latency, throughput, tokens per second per user, or some other metric. Secondary reporting captured in search results suggests Cerebras has described the system as capable of processing “up to 30 times more tokens per second per user than traditional GPU-based systems,” but that detail is not fully resolved in the primary launch materials available here.
The company also has not made all commercial terms obvious in the public material we reviewed. We did not find pricing, quota, or a documented migration path for operators deciding whether to move workloads from conventional GPU clouds. That means the practical deployment question remains open: CS-4 may be positioned as an alternative for inference-heavy production workloads, but the launch page alone does not yet show how customers will buy it, where it is generally available, or what capacity constraints apply.
Cerebras’ messaging fits a broader market shift toward inference as the main value pool in AI infrastructure. Inference is where models are actually run in production, and cloud providers, chip vendors and model startups are increasingly competing on tokens per dollar rather than training-scale bragging rights. The company’s current framing is therefore familiar: a specialized stack promising better throughput and lower cost than general-purpose GPU clouds.
For buyers, the immediate implication is straightforward. If Cerebras’ claim holds up under independent testing, CS-4 could become a serious option for inference workloads where speed and per-request efficiency matter more than flexibility. But without a published benchmark methodology, the launch should be read as a vendor claim, not a market verdict.
The closest incumbent comparison is the standard GPU cloud stack Cerebras is explicitly targeting. That includes the generic infrastructure model used by mainstream cloud providers and specialized GPU clouds alike. For now, Cerebras is asking the market to judge CS-4 on its own numbers.
What Cerebras says CS-4 is for
- Rack-scale AI inference
- Running leading models in production
- Lower infrastructure cost than GPU clouds
- Higher inference throughput than traditional GPU-based systems
What is not yet fully documented
- Exact benchmark methodology
- Specific comparison hardware
- Pricing
- General availability status
- Migration guidance for operators
Cerebras’ launch page makes the pitch simple: buy inference speed, not general-purpose flexibility. The remaining question is whether the company can back the 30x claim with enough detail to let customers compare it on equal terms with GPU alternatives.
Comments ()