Project Maya’s Latest Release Speeds DeepSeek Inference on NVIDIA and AMD Rigs
Project Maya’s latest release packages a 748B DeepSeek build and claims faster inference when RAM can hold the experts.
Project Maya’s latest release is aimed at one practical problem: how to make a very large open model easier to run on real hardware. In v1.1.27, maintainer mw00 says the project now packages DeepSeek V4.1-Flash-1017 as a 748B quantized release for NVIDIA and AMD inference, with support across Linux and Windows. The release notes say the work is intended to improve deployment flexibility without forcing developers into hyperscaler defaults.
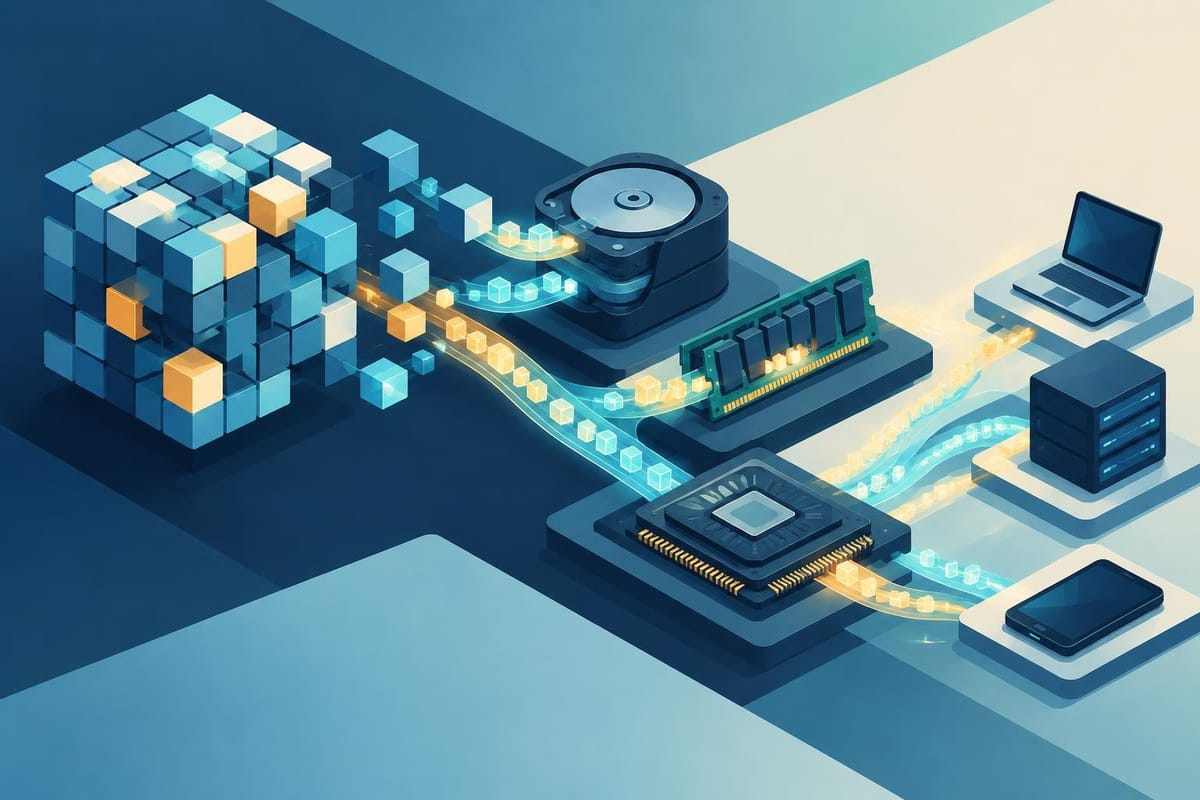
According to the release page, the update also changes how the model handles memory when enough RAM is available. The maintainer says --mmap-experts auto now copies GGUF CPU-lane experts into RAM when all of them fit with room to spare, instead of rereading them from disk every token. In the release notes, Project Maya says that behavior produced reported gains of about 22% on four V100s with 504 GB of RAM, about 2x on a 20 GB card with 255 GB, and about 23% on four RTX 3090s with 126 GB, with a similar gain on three V100s in the maintainer’s own tests. The release also says that if RAM is tight, nothing changes; a measured copied path was slower, and --mmap-experts on leaves experts in files.
The same release adds support for reading whole videos in GLM workflows, with frames sampled at 4 a second through the picture encoder, but the headline significance here is the DeepSeek packaging. For teams trying to run frontier-scale open models on their own servers, the point is not that a new model suddenly became cheap. It is that inference packaging is getting more hardware-aware, more cross-platform, and more explicit about when memory layout can make or break throughput.
That matters because the release notes frame these as conditional gains, not universal ones. The speedup appears when RAM can hold the experts; otherwise the default behavior is unchanged. The maintainer also ties the Windows and Linux support to specific runtime requirements rather than promising a blanket drop-in path. In other words, Project Maya is making a large model more operationally usable, but it is not claiming that every deployment will see the same result.
For developers, the upgrade path is straightforward: use the new release if you have the RAM headroom to keep experts resident, and keep --mmap-experts on if you prefer file-backed behavior. The practical takeaway is narrower and more useful than a benchmark headline: open-model inference is moving from raw model availability toward packaging that actually respects the hardware it will run on.
Source: https://github.com/mw00/project-maya/releases
Comments ()