Thinking Machines releases Inkling 2 Mini for 32GB Macs
Learn how to access Inkling 2 Mini, what hardware it needs and how its coding benchmarks and limitations compare.
Thinking Machines released Inkling 2 Mini on November 20, a 26.4-billion-parameter, open-weight model designed to run locally as well as through an API. Its model card lists an Apache 2.0 license and a context window of up to 1 million tokens.
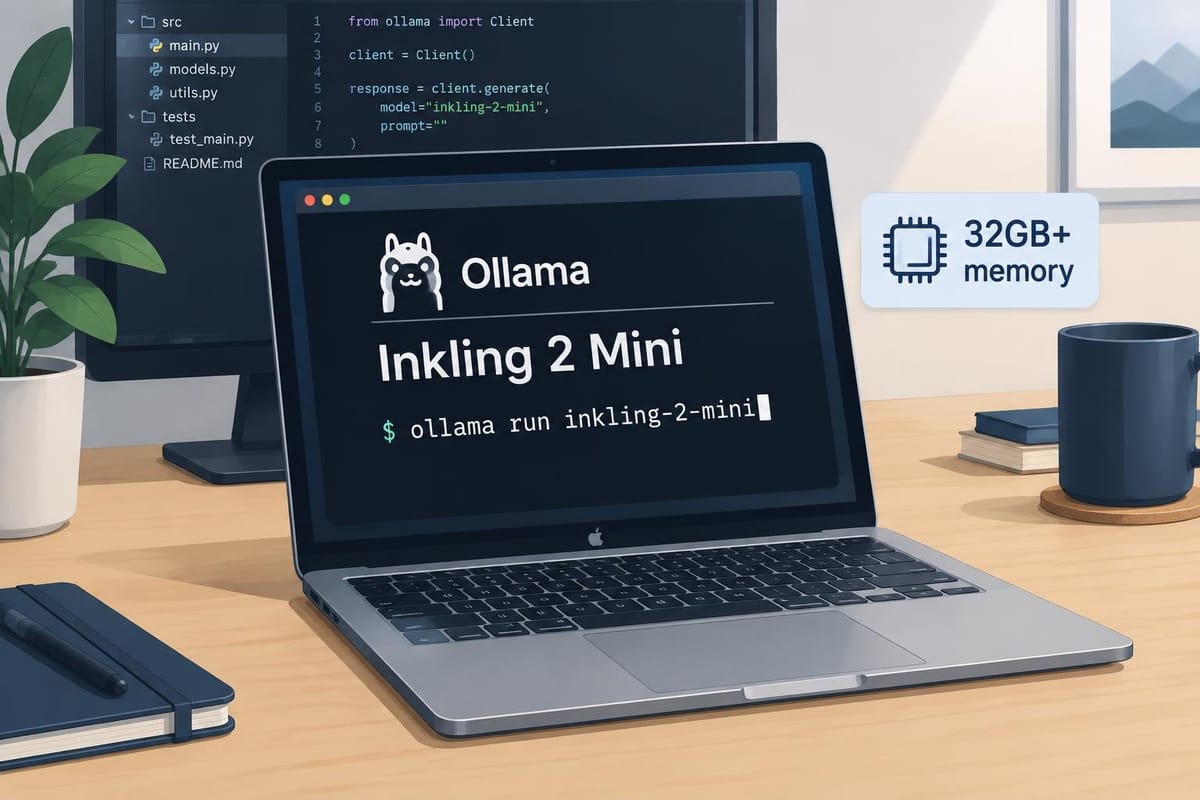
For developers choosing between a hosted model and their own hardware, Mini offers a local option: Thinking Machines says its approximately 20GB checkpoint can run on Apple silicon systems with at least 32GB of memory or an NVIDIA DGX Spark. The company recommends at least 32GB of VRAM for other GPUs. That is the hardware guidance for running the model, not a guarantee that every workload will fit at the full context limit.
The model accepts text and images and produces text. Its weights are on Hugging Face; developers can also use Tinker for inference and fine-tuning or access it through third-party inference providers. API pricing for Mini was not established in the release materials; check the provider’s rate before deployment.
On a qualifying Mac, Ollama’s instructions call for its preview release and the command ollama run inkling-2-mini. The model card also lists SGLang and vLLM among supported frameworks and notes that quantized GGUF versions are available.
Mini is a mixture-of-experts model with 3.4 billion active parameters. It repeats its middle 12 layers three times per token, making the effective computation equivalent to 5.4 billion active parameters per token. Thinking Machines says it pruned two-thirds of the experts during training to reduce size, then used distillation to recover performance.
In the company’s release benchmarks, Mini resolved 48.2% of DeepSWE v1.1 tasks, versus 42.2% for Qwen3.8-27B; the model card lists mini-swe-agent v2.4.6 for that evaluation. The company cautions that evaluation setups vary by model. Its published speed comparison is a theoretical decoding ceiling, not a measured laptop throughput result.
The smaller footprint comes with a quality tradeoff. The model card says Mini is less capable than the larger Inkling 2 Small across most evaluations, with the largest gaps in factual recall and knowledge-heavy questions. Thinking Machines also says Mini trails Qwen3.8-27B on multi-turn chat and complex instruction following.
Comments ()